The open platform
for every layer of voice,
music, and media creation.
Studio-grade neural voice synthesis, multi-track music production, and visual media creation on self-hosted GPU infrastructure.
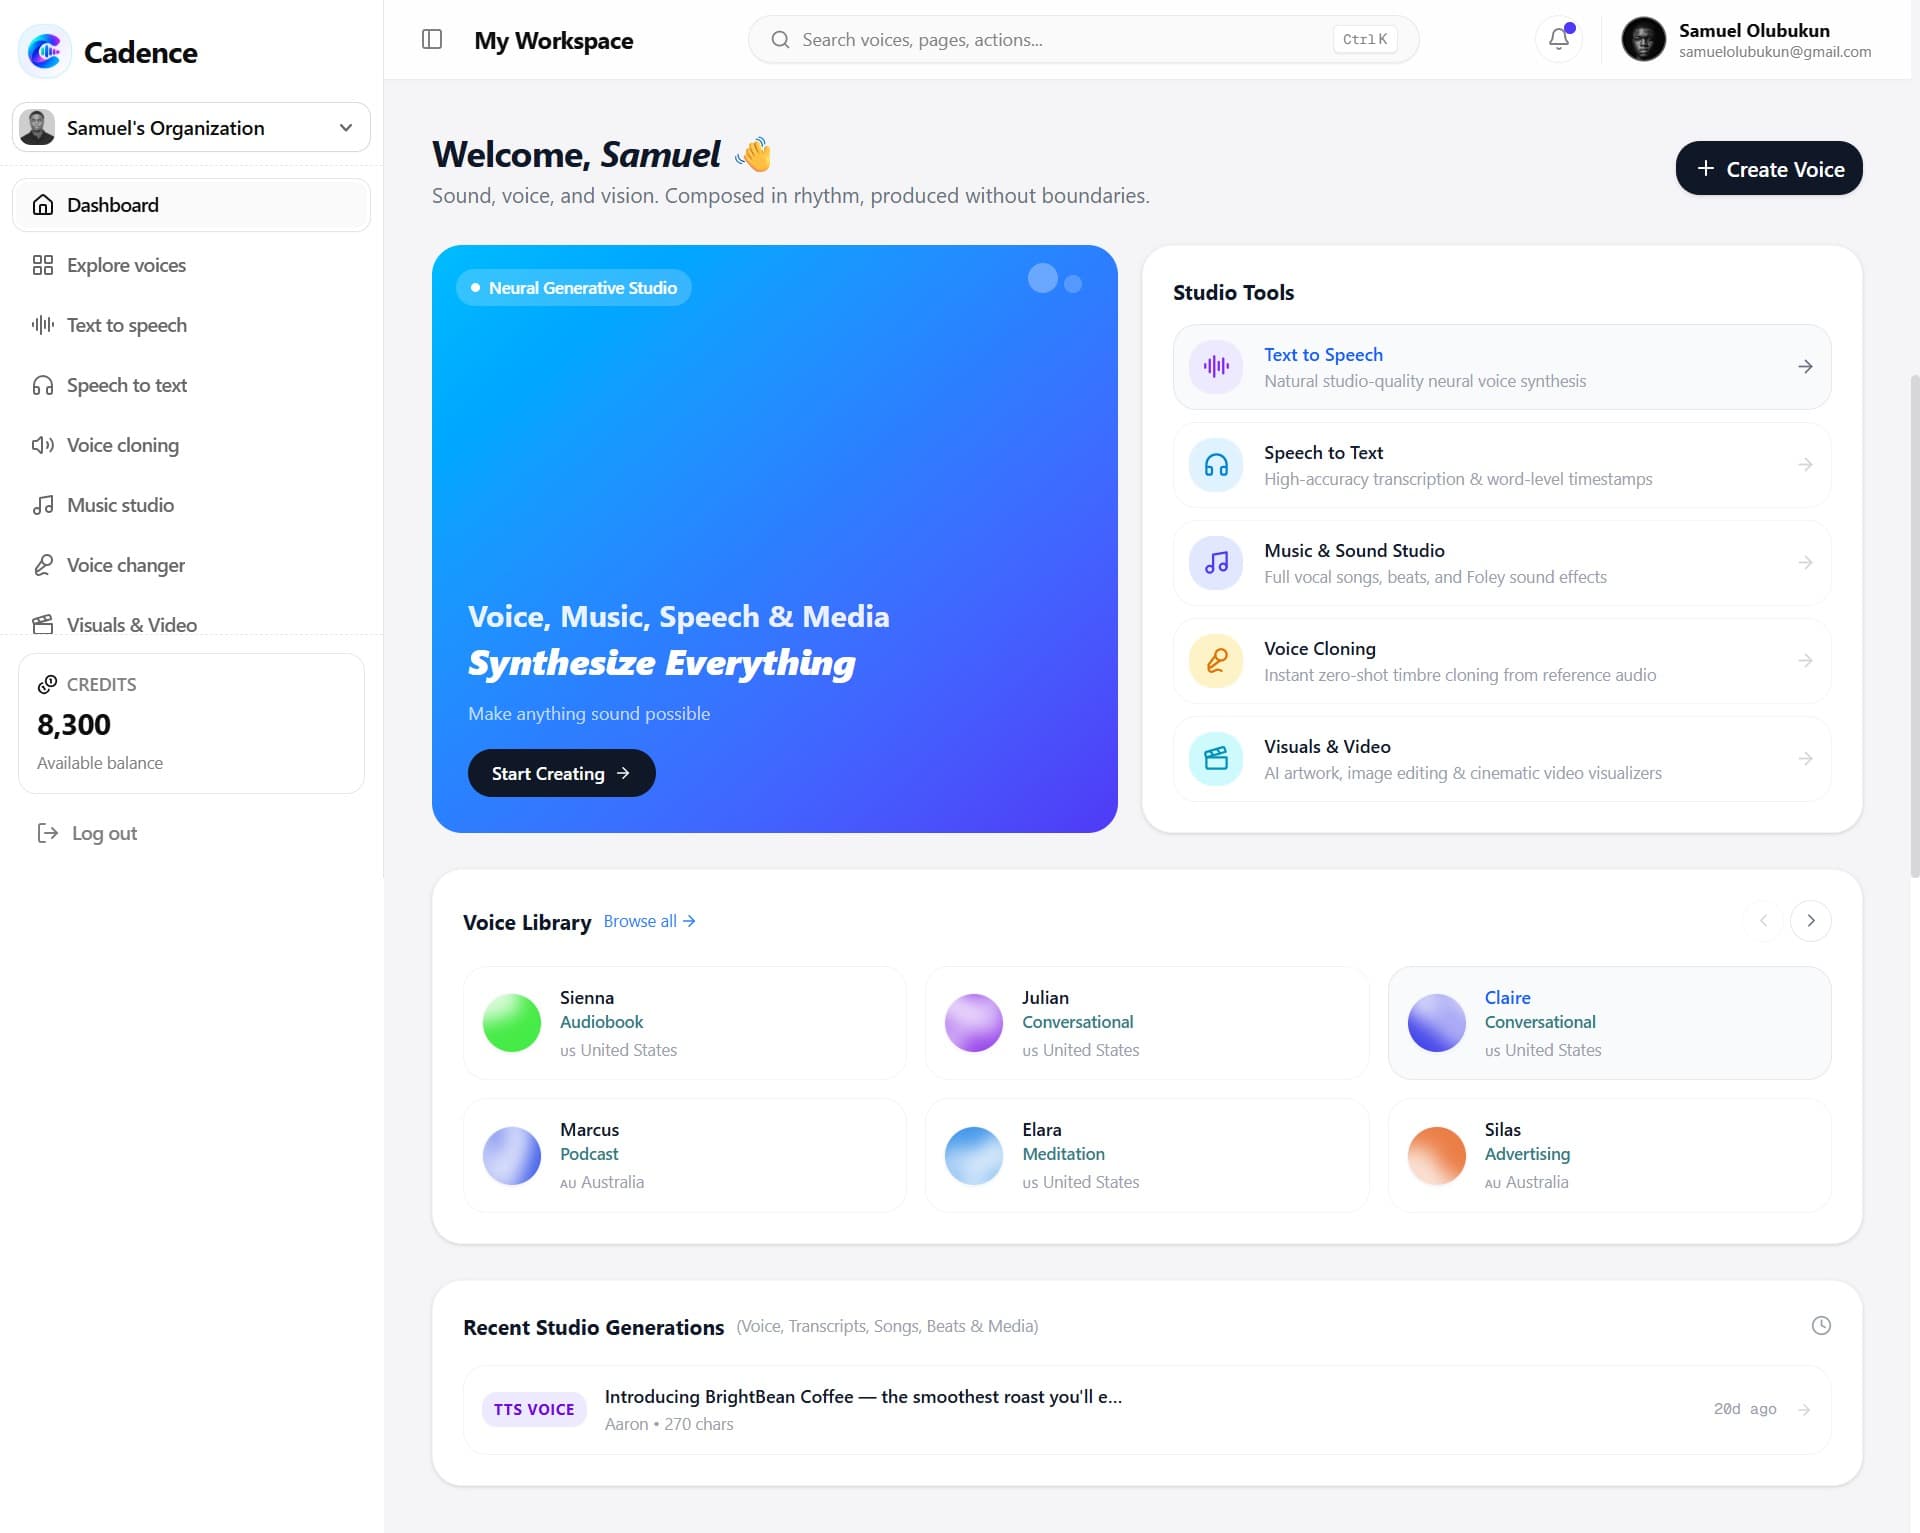
The open creative platform for voice, music & media
Built entirely on open foundation weights and self-hosted serverless GPU infrastructure. Complete ownership of your models, sub-second latency, and zero vendor lock-in.
Unrestricted Open-Source Foundation Models
Cadence brings state-of-the-art weights directly to your studio. No black-box closed APIs, no sudden feature deprecations, and no arbitrary rate limit shutdowns.
Modal Cloud & Docker On-Prem
Run on serverless NVIDIA A10G GPUs with instant scale-to-zero, or self-host completely air-gapped using modular Docker Compose microservices.
Your Voiceprints Stay Yours
Cloned reference audio, generated stems, and transcripts reside in your private Cloudflare R2 bucket protected by short-lived signed URLs.
From Text and Voice to Music and Visuals
Turn text into lifelike speech, clone your own voice from a short audio clip, transform vocal tone with the voice changer, produce custom music tracks, transcribe speech with accurate timestamps, and create visuals for your media.
Powered by Foundation Open Models
Every audio, voice, visual, and video studio in Cadence runs on vetted, self-hosted open source neural weights on serverless NVIDIA A10G GPUs.

Chatterbox Turbo
Resemble AI / Open Weights
Fast multi-speaker speech synthesis with fine emotion and pitch conditioning.

Whisper large-v3
OpenAI Open Source
Robust multilingual transcription and automatic translation at state-of-the-art accuracy.

OpenVoice v2
MyShell AI
Instantaneous timbre morphing while preserving original emotion, rhythm, and intonation.

Meta AudioGen
Meta Audiocraft
Generate photorealistic Foley, studio ambient soundscapes, and cinematic impact effects.

SenseNova-U1.5-8B
SenseTime / Open Weights
State-of-the-art Mixture-of-Transformers for ultra-detailed photorealistic album art, lighting, and textures.

Qwen-Image-2.1
Alibaba Cloud / Open Weights
Next-gen visual foundation model specialized in flawless legible English typography, transparent PNG assets, and multi-image contextual editing.
Meta Demucs v4
Meta AI Research
Deconstruct master tracks into crystal-clean isolated Vocals, Drums, Bass, and Instrumental stems.
RVC v2
Retrieval-based Voice Conversion
Neural singing voice conversion transforming vocal leads and harmonies into any target artist timbre.
Resemble Enhance
Resemble AI
Zero-shot acoustic speech restoration removing background noise, distortion, and microphone artifacts.
Meta MusicGen Melody
Meta Audiocraft
Controllable text-to-music generation guided by harmonic structure and BPM guidance.

ACE-Step 1.5 Turbo
Torchcodec Accelerated
Rhythmic beat creation and complete multi-genre songs complete with structured vocals and lyrics.

SDXL-Turbo
Stability AI
Single-step ultra-fast image generation creating high-res album covers and visual artwork.
Wan2.1 1.3B
Wan-Video Open Model
Cinematic audio-reactive scene generation, dynamic sound wave rendering, and cosmic visualizers.

Kokoro-82M
Hexgrad / Open Weights
Featherweight neural speech engine delivering studio-grade voice generation at extreme conversational speeds.
Qwen2.5-1.5B
Alibaba Cloud / Open Weights
Ultra-responsive reasoning model driving real-time agent dialogue, instant barge-in context, and creative answers.
NVIDIA Parakeet
NVIDIA NeMo / FastConformer
Ultra-fast automated speech recognition with state-of-the-art accuracy for instant real-time user transcription.
Ultralytics YOLO11
Ultralytics / Open Weights
High-speed computer vision model powering automatic speaker bounding box tracking and dynamic framing for viral vertical shorts.


Everything you need to generate voice, music & media
Eight dedicated production studios powered by self-hosted open source neural weights on serverless NVIDIA A10G GPUs or on-prem Docker.
Text to Speech
24kHz Neural Synthesis
Sub-second streaming TTS with fine-grained exaggeration and pacing sliders. Generates living human voice without robotic artifacts.
Voice Cloning
Instant 5-Second Voiceprints
Clone any human voice timbre in under 5 seconds from a single WAV reference clip. No fine-tuning or model retraining required.
Speech to Text
Word-Accurate Transcription
Transcribe long-form podcasts, interviews, and lectures in 99+ languages with forced alignment word-level timestamps and subtitle exports.
Music & Sound Studio
Beats, Songs, Stems & AI Singing
Produce full instrumental beats, complete vocal songs, isolate 4-track stems with Demucs v4, and create AI singing covers with RVC v2.
Voice Changer
Speech-to-Speech Timbre Morph
Preserve your exact emotional nuance, pauses, and cadence while instantly morphing your vocal timbre with studio neural denoising.
Viral Video Clipper
Automated 9:16 Shorts Generator
Transform podcasts and long videos into viral vertical shorts. Features Whisper timestamps, Qwen virality scoring, YOLO11 active speaker tracking, and kinetic captions.
Visuals & Video
Studio Art, Typography & Video Loops
Synthesize high-fidelity artwork with legible typography using Qwen-Image-2.1, photorealistic 8B MoT with SenseNova, and cinematic Wan2.1 motion loops.
Voice Agent Studio
Full-Duplex Conversational AI
Talk directly to an ultra-responsive voice assistant with instant Silero barge-in detection, sub-200ms Kokoro TTS, and zero-shot Chatterbox cloned voices.
Built-in System Voices
Listen to studio-grade 24kHz reference voices sourced from the VCTK corpus. Every timbre is calibrated for zero-shot cloning, speech-to-speech, and Chatterbox Turbo neural TTS.
Warm, expressive American female voice ideal for audiobooks and storytelling.
🇺🇸United States
Confident American male narrator with a natural conversational flow.
🇺🇸United States
Relaxed and conversational American female tone, perfect for podcasts.
🇺🇸United States
Laid-back Australian male voice from Sydney, great for casual podcasts.
🇦🇺Australia
Gentle and melodic American delivery, well-suited for meditation and calm narration.
🇺🇸United States
Deep Australian male timbre suited for commercial reads and promotions.
🇦🇺Australia
Cadence vs. Legacy Cloud APIs
No mystery subscriptions. No vendor lock-in. Voice, music, stems, and visual media powered by predictable pay-as-you-go credits.
How Cadence transforms
ideas into broadcast media
From raw script and melodies to studio-grade voice, multi-track music, stem splits, and cinematic visuals. Powered by open foundation models on self-hosted GPU infrastructure.
Broadcast Voice Synthesis Console
Chatterbox neural vocoder and Kokoro neural engine mapping phonetic cadences into emotional speech.
Zero-shot acoustic embedding extracts pitch contours and vocal timbre without requiring lengthy model fine-tuning or training datasets.
Dual cloud serverless and on-prem Docker
Deploy to serverless Modal NVIDIA A10G GPUs with automatic scale-to-zero, or self-host completely on your local workstation via Docker Compose.


Dual Modal Cloud & On-Prem Docker Microservices
Serverless NVIDIA A10G (24GB) Cloud • Local Docker Modular & Monolith Stacks
Run on serverless GPU containers with scale-to-zero ($0.00 idle cost), or launch on-prem with Docker Compose across modular microservices or a unified monolith on NVIDIA RTX gaming rigs and Apple Silicon:
Voice & Speech Engine
Chatterbox Turbo & Whisper large-v3
Cadence Studio Engine
Demucs v4, RVC v2 & Resemble Enhance
Voice Morphing Engine
OpenVoice v2 Engine
Music & Beat Engine
MusicGen, AudioGen & ACE-Step
Studio Image Visuals
Qwen-Image-2.1, SenseNova & SDXL-Turbo
Video Visualizer Engine
Wan2.1 1.3B Diffusion Transformer
Real-Time Voice Agent
Silero VAD, Parakeet, Qwen2.5 & Kokoro
Viral Video Clipper Engine
Whisper v3, Qwen2.5, YOLO11 & NVENC
Universal S3 / R2 / MinIO
Private Bucket • Direct Filesystem Mount
All generated WAV masters, audio stems, reference recordings, and MP4 shorts live in private S3-compatible storage (Cloudflare R2 in cloud, MinIO container locally). Direct Linux filesystem mounting (/r2) enables zero-latency model access.
Convex Real-Time Database
Reactive Subscriptions • Instant State Sync
Convex handles generations metadata, live credit audit ledgers, voice catalog indexing, and organization state. Reactive queries update the dashboard immediately as GPU inference completes.
Edge Security & Tenant Isolation
Clerk Auth • JWT Cryptographic Verification
Cryptographically verified session tokens with automated multi-tenant isolation. Every media download and voice conversion request validates organization boundaries before issuing signed streaming tokens.
Start Creating With Cadence Today.
Zero-shot voice cloning, expressive neural speech, multi-track music, stem separation, and visual media in one studio. No recurring subscriptions, no vendor lock-in. Just pure creative freedom.